
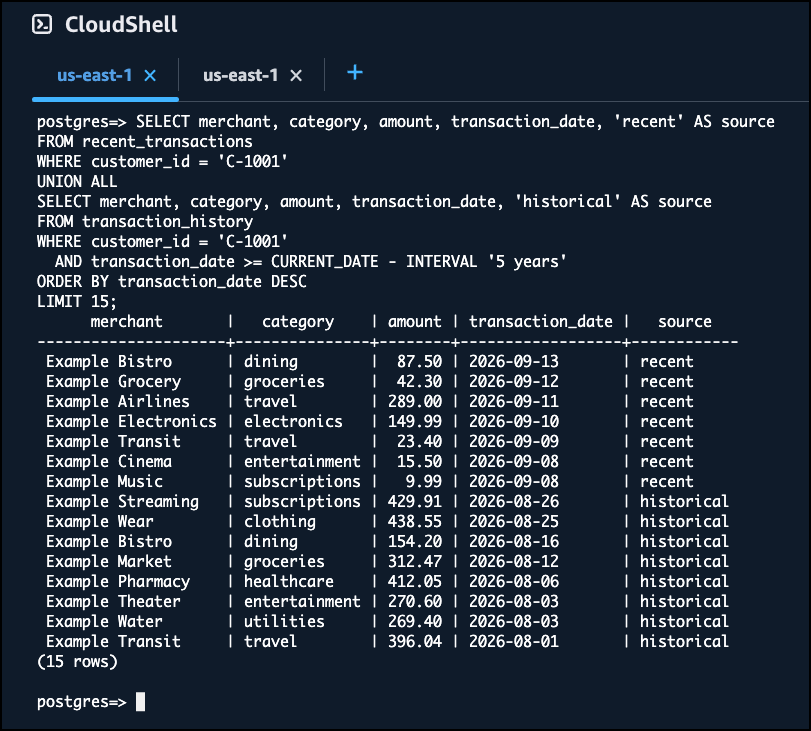
Today, we’re announcing a new capability for Amazon Aurora PostgreSQL that you can use to directly query operational data together with data stored in your data lake in Apache Iceberg and Apache Parquet formats, using your existing PostgreSQL applications and tools. By eliminating the need to extract, transform, and load (ETL) structured data from data lakes into your operational database, you can reduce operational complexity and simplify application development. You can also use Aurora PostgreSQL to query data from data lakes managed in Iceberg REST Catalog (IRC)-compatible catalogs, giving you access to data across a breadth of analytics systems without moving or duplicating it. Whether you’re powering real-time dashboards, enriching transactions with historical context, or building AI agents that reason over both live and archived data, you can now do it all through a single, familiar interface.
Previously, if your application needed to combine recent transactional data in Aurora with historical records stored in Amazon S3, a common approach was to build reverse ETL pipelines that duplicated data, increased infrastructure costs, and required ongoing engineering effort to keep everything synchronized. This challenge only grows as you increasingly embed AI agents into your applications, where it is impractical to predict and pre-replicate every dataset an agent might need.
DuckLabs, the team that maintains the DuckDB project, recently joined Amazon, and this capability is an example of how the efficiency of DuckDB is being integrated into our services. DuckDB is now embedded directly within Aurora PostgreSQL, so you can query live operational data (including uncommitted writes) alongside your data lake in a single query. Query processing stays within Aurora, with no additional network hops and no ETL pipelines that duplicate data. You can query Apache Iceberg tables managed through the AWS Glue Data Catalog, as well as Parquet and Iceberg data stored in Amazon S3 and S3 Tables. You do all of this using familiar PostgreSQL syntax and your existing applications and tools.
We’re excited to bring the speed and simplicity of DuckDB directly into Aurora PostgreSQL, so you and your agents can query and combine operational and Iceberg data using the familiar PostgreSQL applications, tools, and endpoints already in use. By building this capability around DuckDB, future improvements to the op
…
Source: AWS Blog (Published: Wed, 30 Sep 2026 17:22:31 +0000). Read the full article on the original site.


